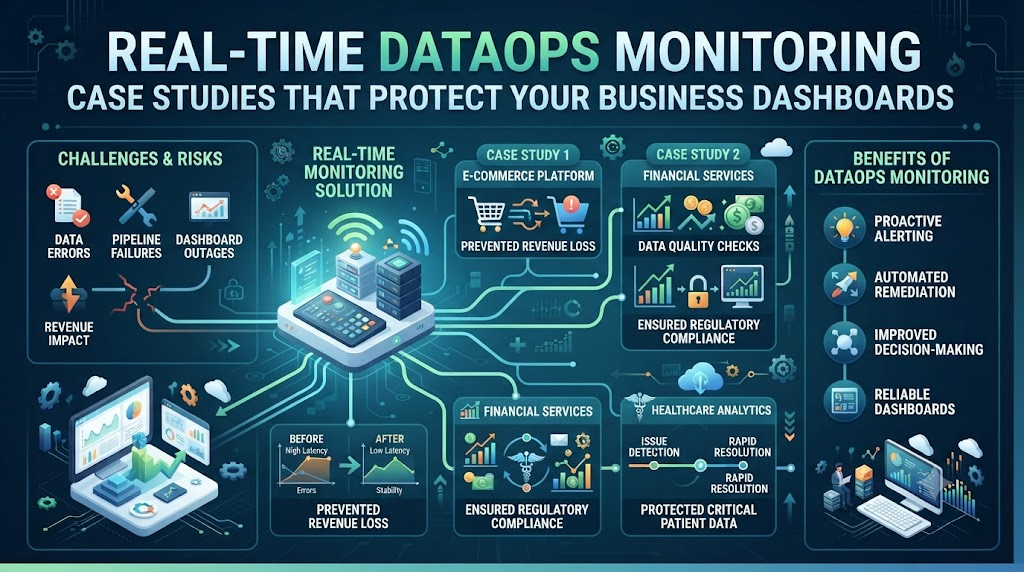
Introduction
Imagine walking into a Monday morning team meeting ready to share great sales numbers. Suddenly, your manager points out that the revenue chart dropped to zero over the weekend. Your stomach drops because you have no idea why it happened. This terrifying scenario happens when data pipelines run blindly in the background.
Business leaders make important choices every day based on incoming metrics. If those numbers are wrong, your company loses money and trust. You need a clear window into how data flows through your systems from start to finish. Watching your data streams live lets you catch hidden errors before anyone else notices them.
To discover helpful professional toolkits and community resources for building safe data workflows, you can visit TheDataOps.org right now. Let us explore fresh case studies and practical steps to secure your company data. We will show you how to keep your reports accurate without living in constant stress.
Understanding Why Data Blind Spots Hurt Companies
Every growing business relies on digital dashboards to track daily progress. When those dashboards break, your entire company slows down to a crawl. People start arguing over whose numbers are right instead of doing their actual jobs.
Finding out about broken data from angry customers or upset bosses feels terrible. You spend hours digging through confusing log files just to find a single missing table column. Proactive tracking stops this painful cycle before it even starts.
The Hidden Dangers of Delayed Analytics
Old data systems usually run heavy checks once a day during the night. If a batch job fails at midnight, you only find out the next morning. By that time, your marketing team has already spent budget on broken campaigns.
Delayed feedback loops destroy your team productivity. Engineers waste valuable hours rewriting bad data loads and fixing historical tables. Moving to continuous observability ensures you catch issues the minute they happen.
Why Old Checking Methods Miss the Point
Traditional data tools rely on very basic row counts to check health. If a table had ten thousand rows yesterday, old tools assume it is healthy today.
However, the actual values inside those rows might be completely broken. Null values, shifted text columns, and currency mismatches slip right past simple row counters. You need deeper tracking that understands the real shape of your data.
How Clean Data Builds Stronger Business Teams
When your data is clean and reliable, everyone works with total confidence. Product managers can launch new features without fearing broken tracking events. Sales teams can trust their weekly pipeline reports without second-guessing every single digit.
Reliable data creates a healthy culture of trust across your entire organization. Your engineers stop playing defense and start building great features that help your customers win.
Core Pieces of Live Data Tracking Systems
An effective monitoring setup focuses on four main areas. First, freshness checks if your data arrives on time every single day. Second, distribution verifies that your numbers stay within normal historical bounds.
Third, volume tracking watches out for sudden drops or massive spikes in data size. Fourth, schema monitoring alerts you instantly when database columns change or vanish without warning.
Cutting Through Alert Noise and Confusion
Getting flooded with hundreds of false alarms makes your team ignore every notification. Good monitoring systems use smart thresholds to cut through useless noise.
You only get pinged when a real, actionable problem happens. This keeps your engineers focused on building products instead of constantly chasing phantom system alerts.
Key Metrics That Every Analyst Should Watch
You do not need to track every single metric to keep your systems healthy. Focus closely on data latency, error rates, and query runtimes.
Data latency tells you how fresh your processed numbers really are. Error rates show how often your transformation jobs fail. Query runtimes help you spot performance slowdowns before your servers crash.
Real-World Story About Data Crises and Business Saves
Here are ten detailed scenarios showing how real-time monitoring solves major business data crises:
- Scenario 1: A sudden memory leak on a production database server caused customer sign-up logs to freeze completely. Real-time CPU tracking triggered an instant alert, allowing engineers to restart the service before data backlog corrupted downstream analytics tables.
- Scenario 2: An external payment partner changed their JSON response format without warning. Pipeline schema monitors detected the missing transaction field within seconds and paused ingestion, preventing corrupt null values from breaking the executive revenue dashboard.
- Scenario 3: A massive influx of duplicate tracking events overwhelmed the data warehouse staging area and threatened cloud storage limits. Volume anomaly detection spotted the spike early and automatically throttled the incoming data stream safely.
- Scenario 4: A routine SQL transformation script entered an infinite loop due to an unhandled join condition. Runtime duration tracking flagged the hanging query at the five-minute mark, letting the on-call engineer kill the process before warehouse compute credits ran out.
- Scenario 5: Network connection issues between cloud regions caused customer event packets to drop silently during peak afternoon traffic. Freshness alerts noticed that the main user activity table had not updated in over an hour and paged the team immediately.
- Scenario 6: A software release introduced a silent bug that converted all customer subscription prices to zero. Distribution monitoring caught the sudden drop in average order value and stopped the reporting cycle instantly.
- Scenario 7: An expired security token blocked access to the primary data lake bucket. Real-time authentication error logs triggered an automated webhook that refreshed the credentials without requiring human intervention.
- Scenario 8: A rogue background process consumed all available disk speed on the primary analytics node. Automated health checks detected slow read speeds and redirected incoming dashboard traffic to a warm backup server safely.
- Scenario 9: A corrupted database partition file caused downstream BI reports to throw confusing syntax errors. Metadata validation monitors isolated the exact bad file partition and rolled back the transaction instantly.
- Scenario 10: A sudden viral marketing campaign overloaded the real-time event streaming queue. Lag monitoring detected the growing consumer delay and spun up additional worker nodes to clear the backlog in minutes.
Comparing Legacy Batch Checks vs. Modern DataOps
| Feature | Legacy Batch Monitoring | Real-Time DataOps Monitoring |
| Detection Speed | Hours after job completion | Seconds during active execution |
| Alert Accuracy | High false-positive rate | Smart thresholds, low alert fatigue |
| Root Cause Analysis | Manual log diving | Automated lineage tracing |
| User Impact | Discovered by angry executives | Fixed before users ever notice |
| Resource Overhead | Heavy daily database scans | Lightweight continuous checks |
Common Mistakes and Pitfalls in Data Monitoring
Here are ten common mistakes data teams make and how you can fix them:
- Mistake 1: Monitoring only row counts instead of checking actual data quality.
- Fix: Add semantic checks for null values, duplicates, and expected value ranges.
- Mistake 2: Setting static alert thresholds that break during seasonal business traffic changes.
- Fix: Use dynamic thresholds that learn normal patterns over time automatically.
- Mistake 3: Sending every single minor warning to the main company chat channel.
- Fix: Route critical alerts to the on-call rotation and low-priority notices to email digests.
- Mistake 4: Ignoring data lineage and guessing blindly where errors originated.
- Fix: Implement automated data lineage mapping to trace issues from source to dashboard.
- Mistake 5: Waiting until morning review to check overnight pipeline runs.
- Fix: Set up real-time push notifications for critical pipeline failures.
- Mistake 6: Hardcoding validation rules directly inside fragile SQL script files.
- Fix: Use dedicated observability tools and modular testing frameworks instead.
- Mistake 7: Failing to monitor cloud resource compute costs alongside data metrics.
- Fix: Track query compute costs in real time to prevent surprise monthly bills.
- Mistake 8: Treating data monitoring as a one-time project instead of an ongoing practice.
- Fix: Assign clear ownership and review alert health rules every month.
- Mistake 9: Overcomplicating setup with heavy enterprise software that takes months to deploy.
- Fix: Start with lightweight open-source checks and scale up gradually as needed.
- Mistake 10: Neglecting to document incident responses and team post-mortem learnings.
- Fix: Maintain a shared team runbook for common pipeline failure modes.
Step-by-Step Implementation Roadmap
Follow these ten sequential steps to build a bulletproof real-time monitoring system:
- Map Your Data Flow: Audit all your current data sources, transformation scripts, and end-user dashboards to understand your complete pipeline architecture.
- Define Critical Assets: Identify the top ten core tables that drive your company revenue and executive decision-making.
- Establish Baseline Metrics: Measure normal data freshness, expected row volumes, and standard query execution times over a two-week baseline period.
- Choose Your Observability Tools: Select lightweight monitoring frameworks that integrate smoothly with your existing data warehouse and orchestration tools.
- Set Up Freshness Monitors: Configure simple time-based alerts to notify you if critical tables fail to update on schedule.
- Implement Schema Validation: Add automated checks to catch unexpected column deletions, type changes, or added fields instantly.
- Configure Distribution Rules: Write custom checks for key business metrics to catch abnormal zeros, negative numbers, or extreme outliers.
- Tune Alert Routing: Connect your alert system to your team communication channels and set up clear on-call rotation schedules.
- Build Incident Runbooks: Create short, step-by-step guides for engineers to follow when specific pipeline alerts fire.
- Review and Refine: Hold monthly retrospective meetings to review alert accuracy, remove noisy checks, and update your runbooks.
Frequently Asked Questions
1. What is real-time DataOps monitoring?
Real-time DataOps monitoring is the continuous tracking of data pipelines as data moves from sources to dashboards, helping teams catch errors instantly.
2. How does real-time monitoring differ from batch checking?
Batch checking runs once a day after jobs finish, while real-time monitoring checks data streams continuously while jobs are running.
3. Do I need expensive tools to start monitoring?
No, you can start with simple custom scripts or open-source testing tools before investing in enterprise platforms.
4. How many metrics should my team track?
Focus on a few core metrics like data freshness, volume anomalies, schema changes, and error rates to avoid alert fatigue.
5. What causes most data pipeline failures?
Upstream schema changes from external APIs and sudden spikes in data volume are the most common causes of pipeline crashes.
6. How do I stop annoying false alarms?
Use dynamic statistical thresholds that adapt to normal business cycles instead of rigid static numbers.
7. Who should be responsible for data observability?
Data engineers, analytics engineers, and data analysts should share responsibility for maintaining pipeline health and data quality.
8. What is data lineage and why does it matter?
Data lineage shows the exact path data takes from source to destination, helping you find the root cause of errors quickly.
9. How does monitoring improve company trust?
Catching bad data before executives see it ensures that business reports remain accurate and trustworthy.
10. What is the best way to begin implementation?
Start by identifying your three most critical revenue dashboards and build basic freshness checks around their underlying tables.
Final Recommendation and Next Steps
Do not try to monitor every single table in your warehouse on day one. Start small by picking your three most important business dashboards. Set up basic freshness and volume checks for those specific tables.
Once your team gets comfortable handling those initial alerts, expand your monitoring coverage step by step. Building reliable data pipelines is a journey of continuous improvement. Take the first step today and secure your core data flow.
